
AI agent development for systems that have to run in production
We build agents that do real work on real data: they plan, call tools, check their own output and report what they did. Fourteen AI platforms shipped so far, and most of what we build is in production today.
An agent demo is a prompt and a loop. An agent in production is mostly everything around the loop: the tools it is allowed to call, the checks that catch a wrong answer before a customer sees it, the budget that stops a run from spending without limit, and the logs that let you explain a decision afterwards.
That surrounding work is what we are hired for. We have built multi-agent research for tax professionals, autonomous agents that test online stores the way a shopper would, and a backend that runs the same workflow on several model providers.
Scope
What we build
Multi-agent orchestration
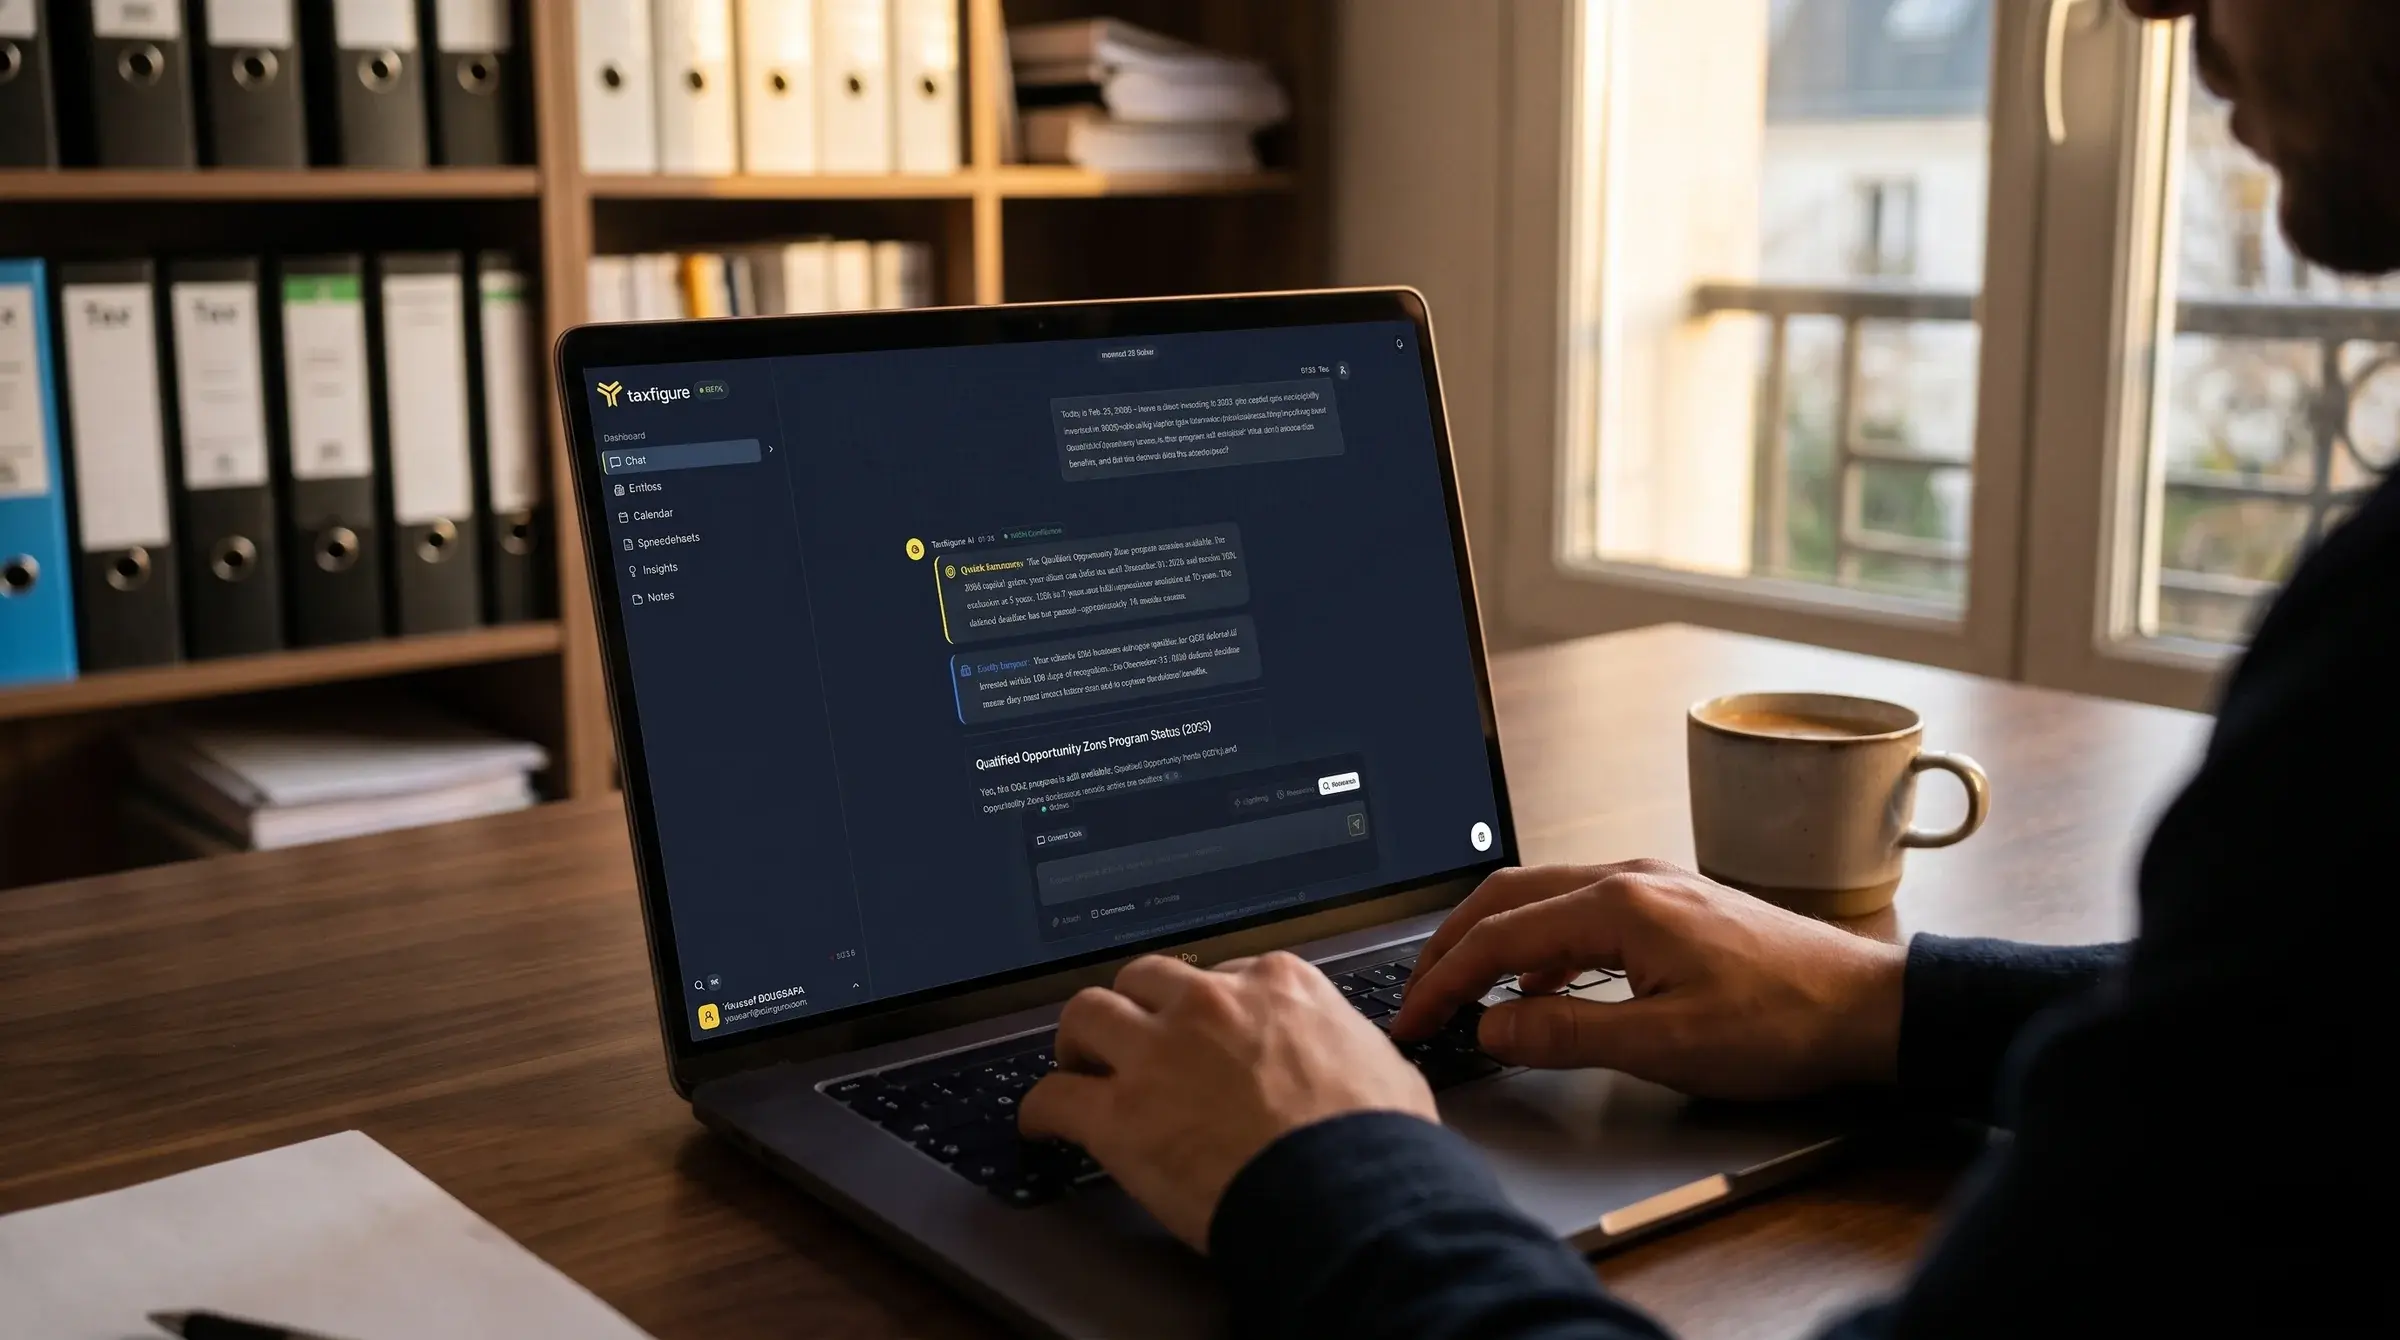
A coordinator that splits a job into sub-tasks, specialized agents that run them in parallel, and a synthesis step that assembles one answer. This is the architecture behind TaxFigure's research engine.
Tool-using agents
Agents that act through tools you define: your APIs, your database, a browser, a document parser. Each tool has a narrow contract, so you know what the agent can and cannot touch.
Verification loops
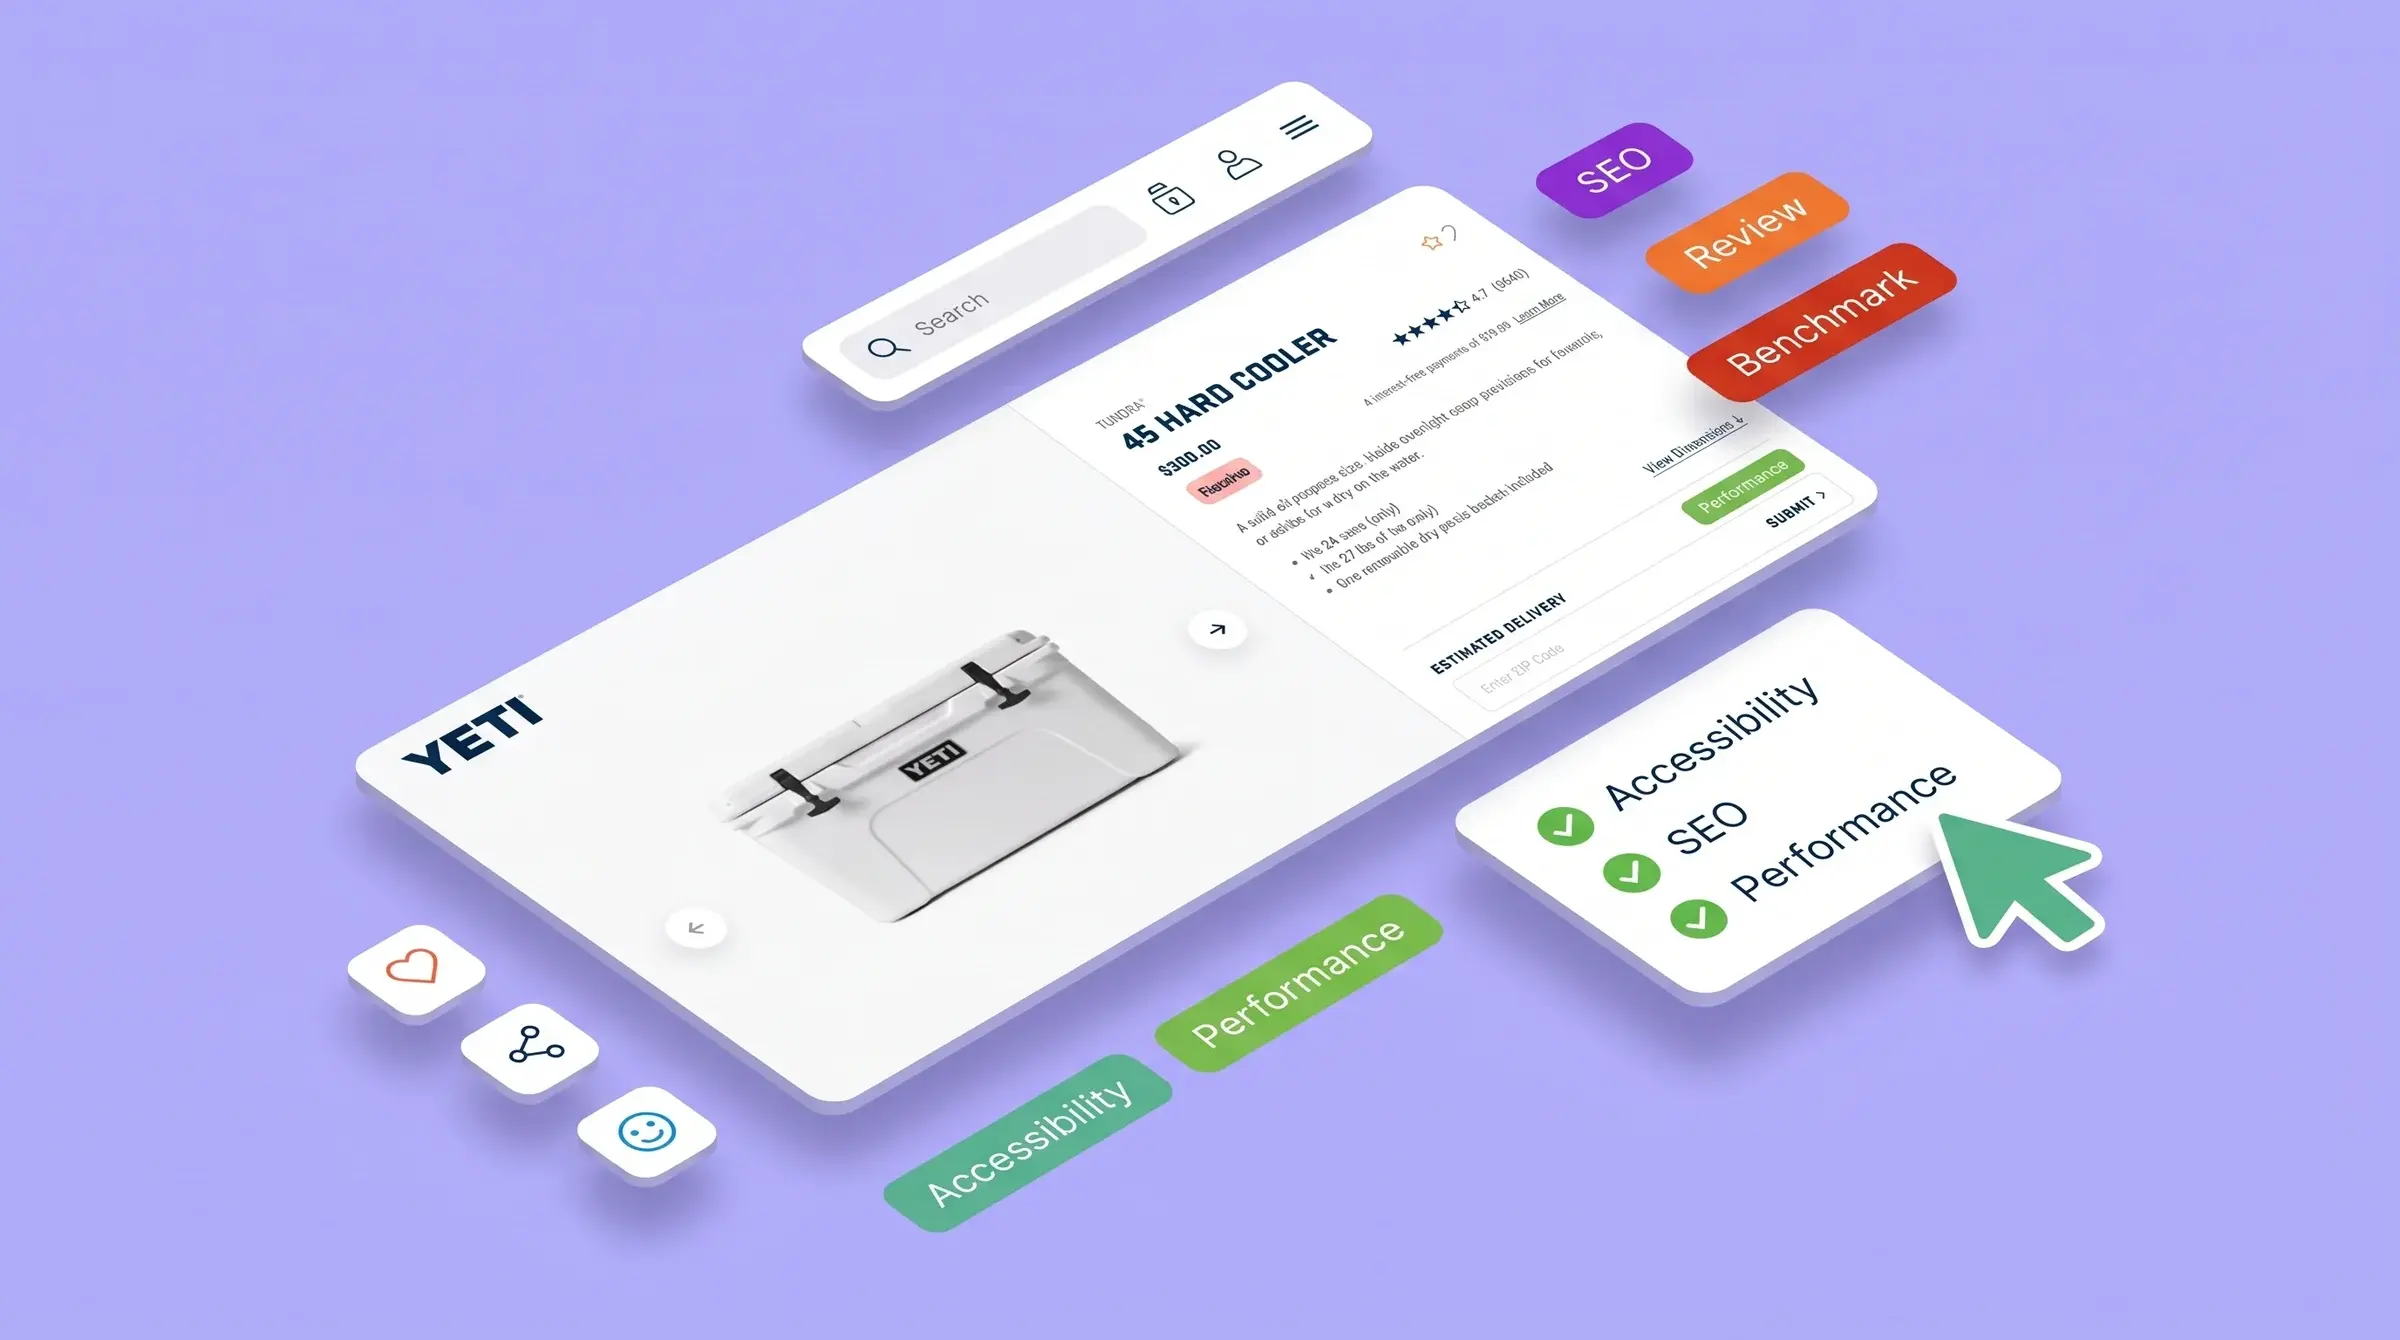
A second pass that re-checks a finding before it is reported. On Zenyt, every potential issue is investigated again with screenshot proof, which filters out false positives before anything reaches the team.
Model routing
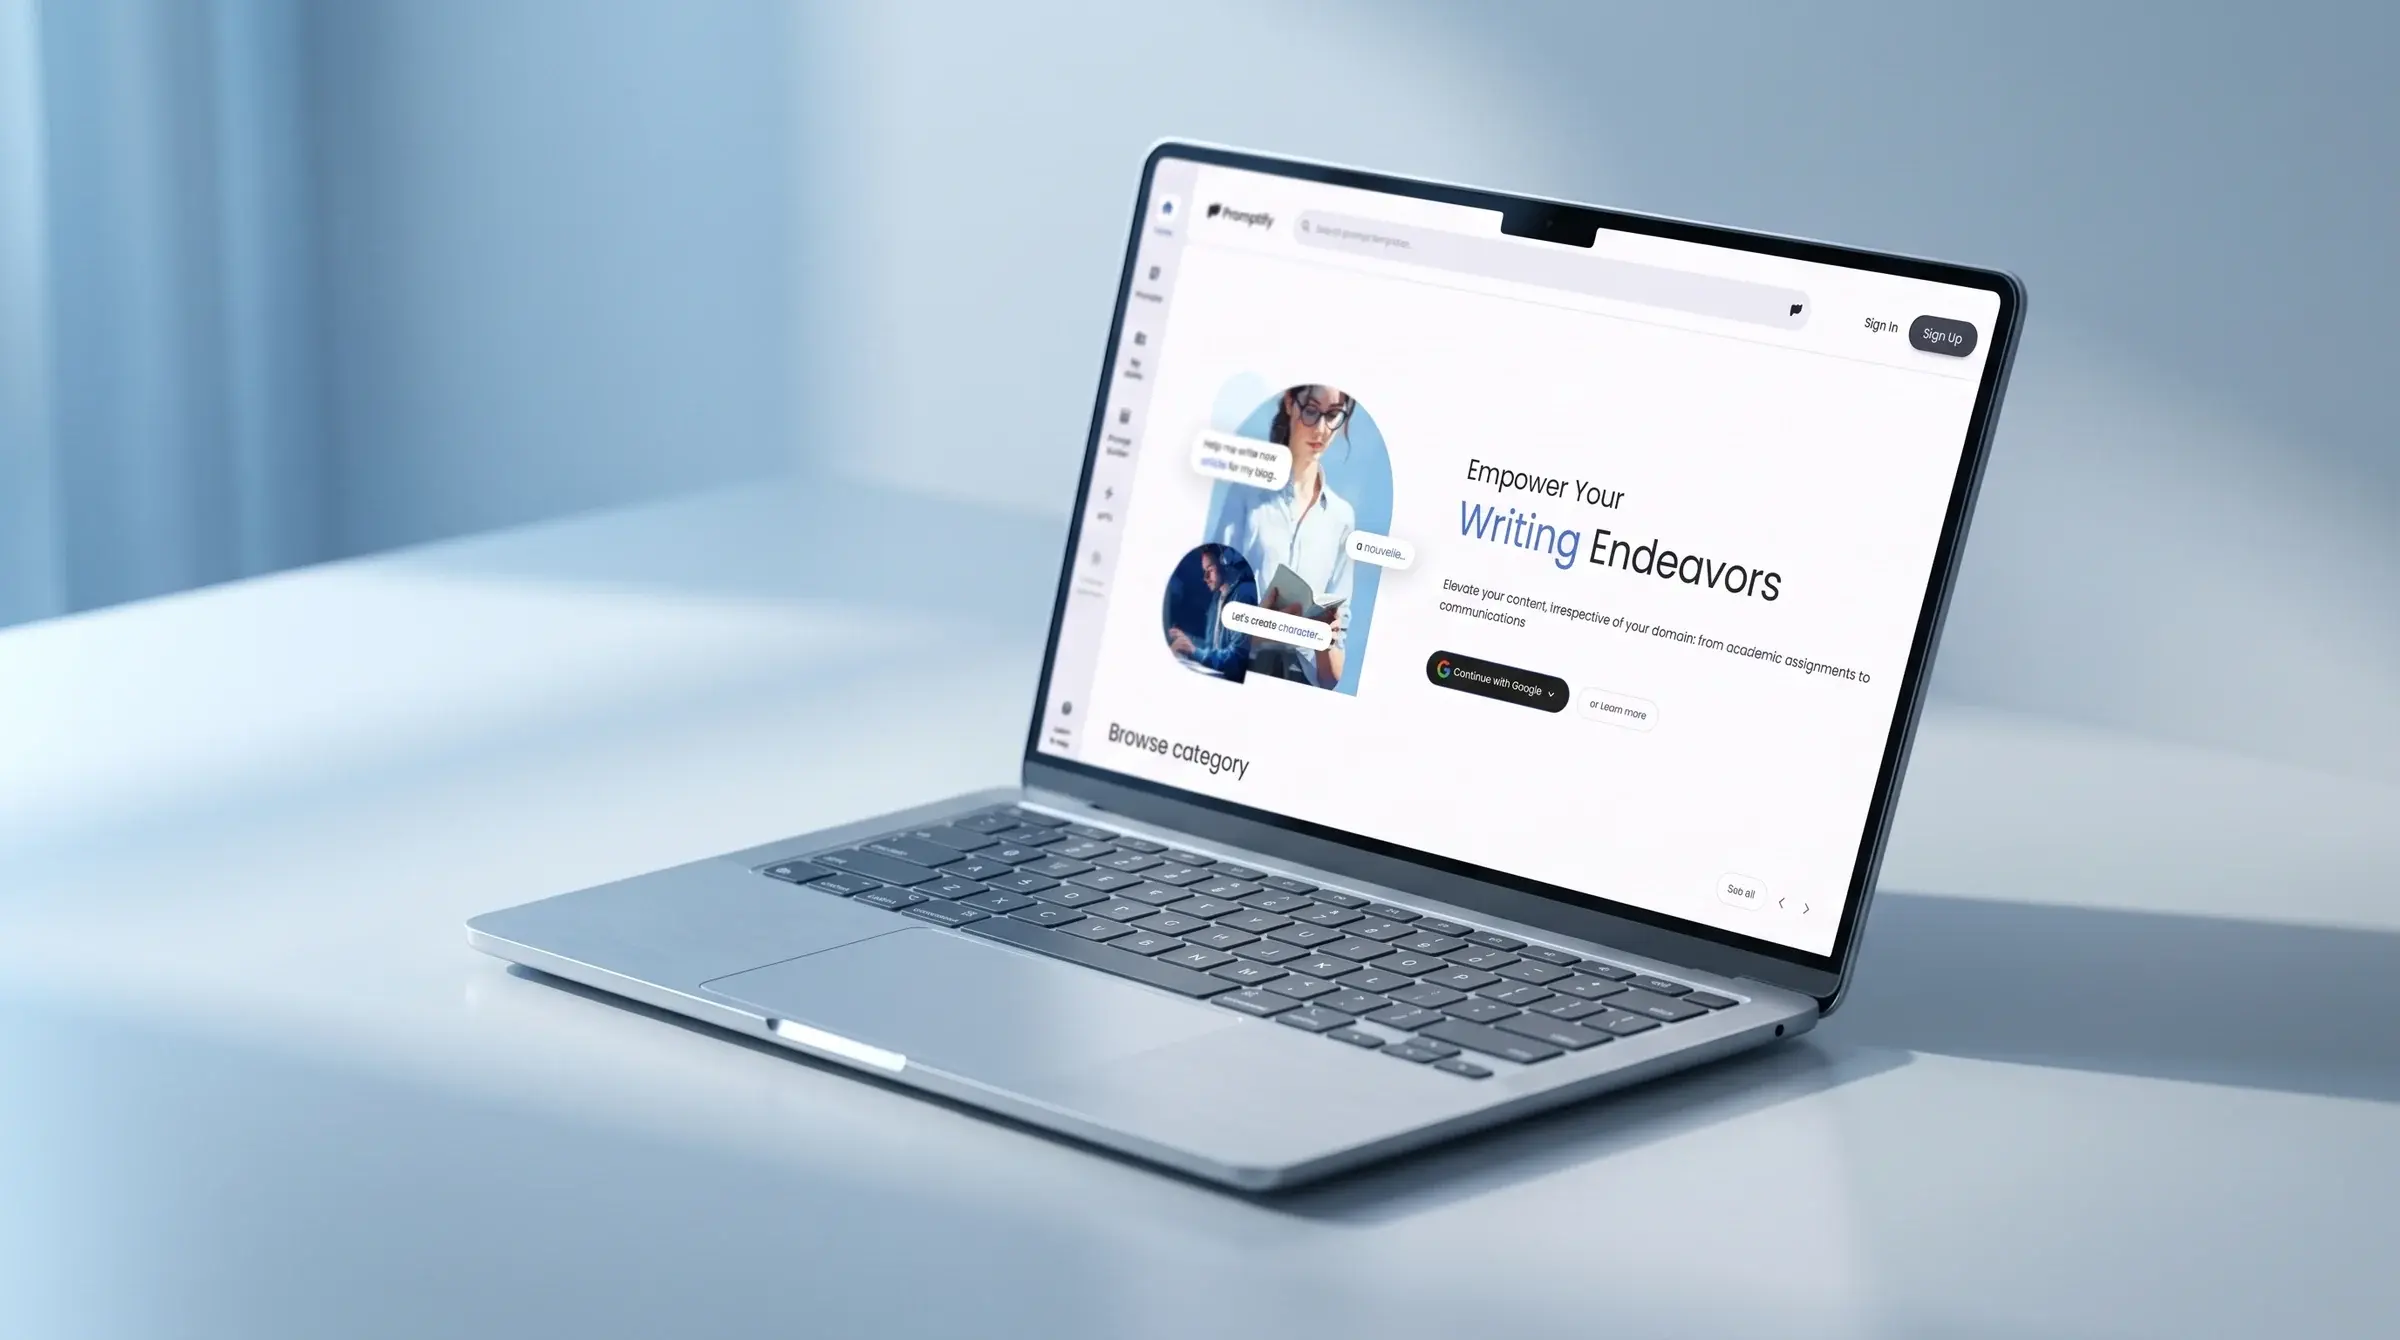
One interface in front of several providers, so the model can change without the product changing. On Promptify, adding a provider is a backend change.
Evaluation and cost controls
Test sets built from your own cases, per-run budgets, and fallbacks when a model fails or a price changes. We plan these in the first architecture review, not after launch.
Monitoring and handover
Logs for every run, a runbook for every agent, and documentation your team can use. After handover, you own the system.
Process
How we work
- 01
Start from the task, not the model
We write down what the agent must do, what it must never do, and how you will know it worked. The architecture follows from that.
- 02
Working software early
You see an agent running on your data in the first weeks, with its failures visible. We would rather show you working software in the second week than a roadmap in the sixth.
- 03
Test on your workload
We test for accuracy, latency, edge cases and failure modes on real data. We do not ship until it works reliably on your actual workload, not a synthetic benchmark.
- 04
Ship, monitor, hand over
We deploy to production, watch it under real traffic and tune it, then hand over the code, the documentation and the monitoring.
Proof
Agent systems we have shipped
FAQ
Questions we get about this.
- Which models and frameworks do you use?
- Whichever fits the job: OpenAI, Anthropic, Google, Mistral, Cohere and open-weight models, often with routing between them. LangChain is in several of our production systems. The choice is made in the architecture review and written down with the reasons.
- How long does it take to build an agent?
- It depends on the number of tools, the quality bar and how much of your data is ready. We scope it after a first call and agree milestones and success criteria in writing before we start.
- What does it cost?
- We do not publish fixed prices, because scope drives the quote. Our article on what an AI agent costs to build and run explains what moves the number, with a worked example.
- Can you work with sensitive or regulated data?
- Yes. We have built a compliance platform for French financial institutions, a GRC platform, and a privacy vault that tokenizes personal data before it reaches an LLM.
- Who owns the code?
- You do. We hand over the code, the documentation and the runbooks, and your team can run the system without us.
Other services
Tell us where the project stands.
We reply to every inquiry within 24 hours. Every engagement starts with a conversation.
Start a conversation